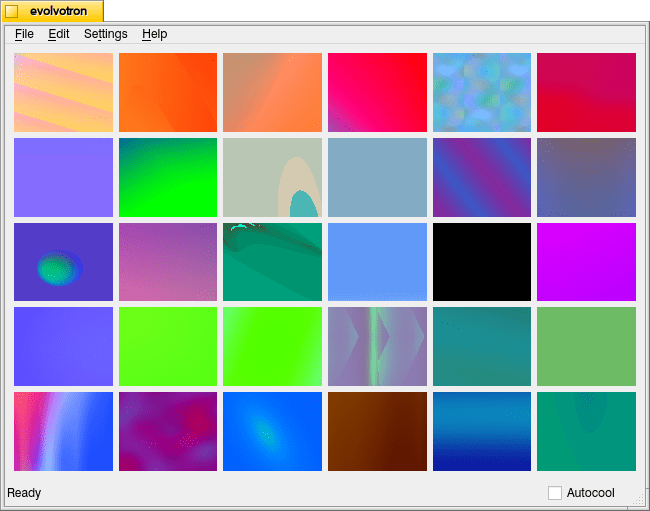
Another such image generator program is Evolvotron. It can generate fractal-based images with different patterns, colors, and shapes.
It has an interactive interface driven by user choices in response to a field of different images–each generated from a different set of parameters. Based on this initial field of images, the user can choose File > Reset (or press R on the keyboard) to generate a new field of images.
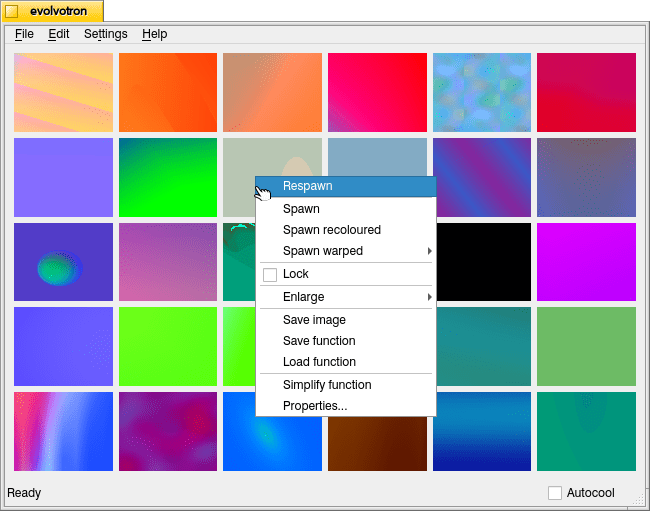
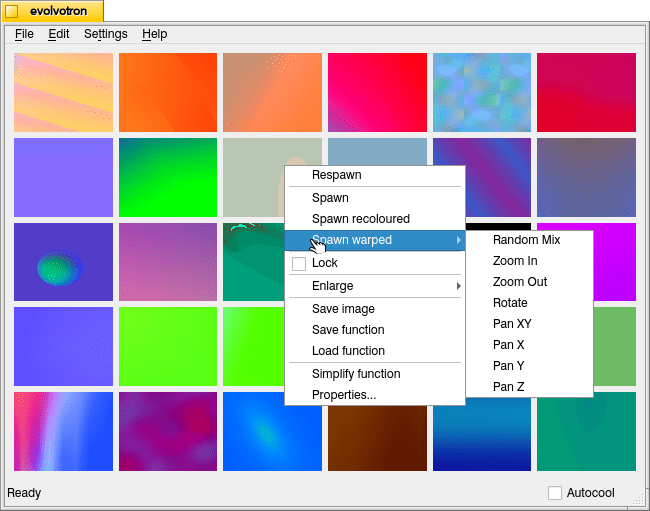
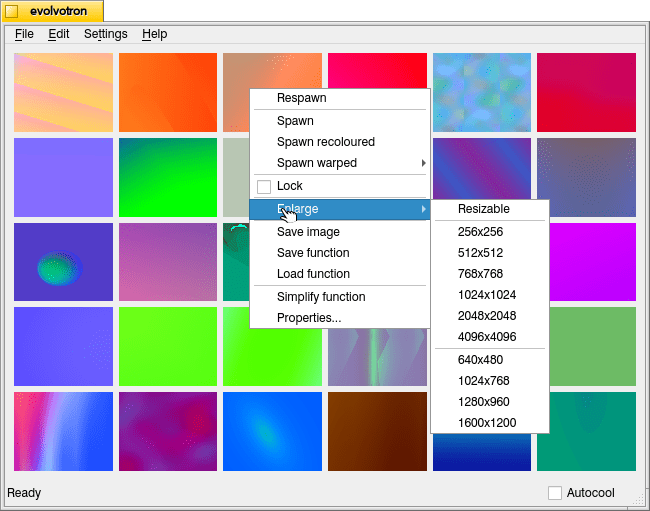
When one of these images is one that the user likes or would like to explore more, they can right click and choose to Respawn (just the one square), Spawn (generate images with adjacent parameters), Spawn recoloured (same originating parameters but different colors), and other functions such as Spawn warped (below), Enlarge (below), and Save.
Below are a few images at 1024 x 1024 that I generated with Evolvotron.
I installed Evolvotron from the Debian 12 repositories. It can also be downloaded for various Linux distributions here, and it is available for MacOS X via Fink.
An anthropomorphic cat wearing coveralls, working with advanced computers. Image generated with Stable Diffusion.
As I wrote about recently about my summertime studying and documented on my generative artificial intelligence (AI) bibliography, I am learning all that I can about AI–how it’s made, how we should critique it, how we can use it, and how we can teach with it. As with any new technology, the more that we know about it, the better equipped we are to master it and debate it in the public sphere. I don’t think that fear and ignorance about a new technology are good positions to take.
I see, like many others do, that AI as an inevitable step forward with how we use and what we can do with computers. However, I don’t think that these technologies should only be under the purview of big companies and their (predominantly) man-child leaders. Having more money and market control does not mean one is a more ethical practitioner with AI. In fact, it seems that some industry leaders are calling for more governmental oversight and regulation not because they have real worries about AI’s future development but instead because they are in a leadership position in the field and likely can shape how the industry is regulated through industry connections with would-be regulators (i.e., the revolving door of industry-government regulation in other regulatory agencies).
Of course, having no money or market control in AI does not mean one is potentially more ethical with AI either. But, ensuring that there are open, transparent, and democratic AI technologies creates the potential for a less skewed playing field. While there’s the potential for abuse of these technologies, having these available to all creates the possibility for many others to use AI for good. Additionally, if we were to keep AI behind locked doors, only those with access (legally or not) will control the technology, and there’s nothing to stop other countries and good/bad actors in those countries from using AI however they see fit–for good or ill.
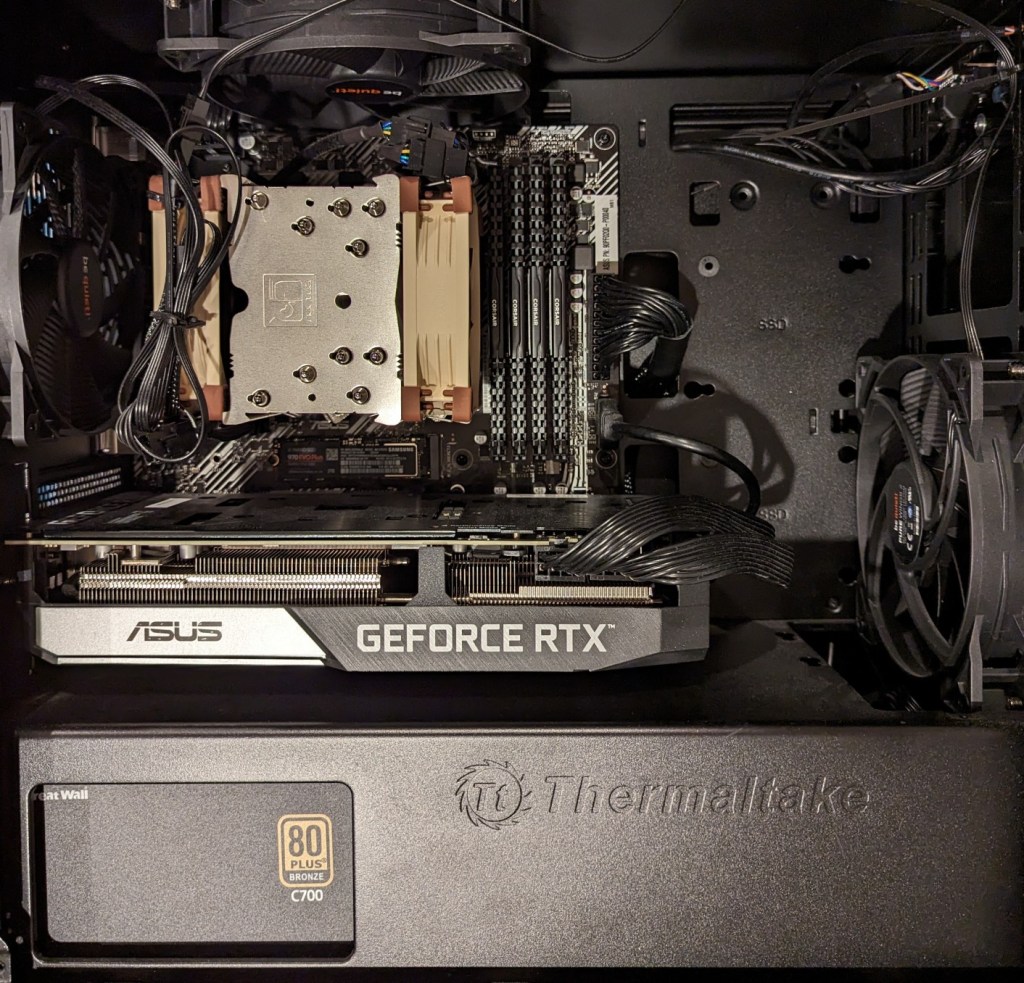
To play my own small role in studying AI, using generative AI, and teaching about AI, I wanted to build my own machine learning-capable workstation. Before I made any upgrades, I maxed out what I could do with a Asus Dual RTX 3070 8GB graphics card and 64GB of RAM for the past few months. I experimented primarily with Stable Diffusion image generation models using Automatic1111’s stable-diffusion-webui and LLaMA text generation models using Georgi Gerganov’s llama.cpp. An 8GB graphics card like the NVIDIA RTX 3070 provides a lot of horsepower with its 5,888 CUDA cores and memory bandwidth across its on-board memory. Unfortunately, the on-board memory is too small for larger models or adjusting models with multiple LORA and the like. For text generation, you can layer some of the model on the graphic’s card memory and your system’s RAM, but this is inefficient and slow in comparison to having the entire model loaded in the graphics card’s memory. Therefore, a video card with a significant amount of VRAM is a better solution.
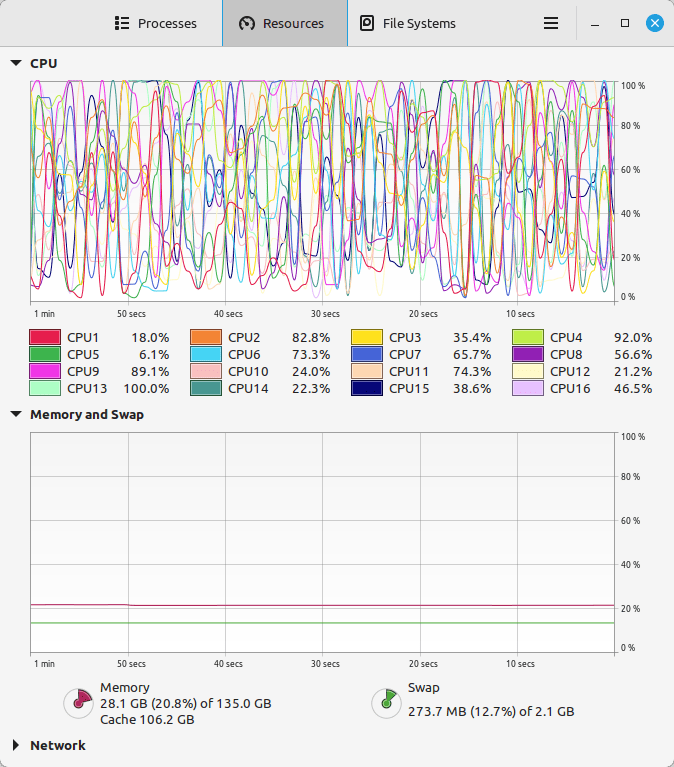
For my machine learning focused upgrade, I first swapped out my system RAM for 128GB DDR4-3200 (4 x 32GB Corsair shown above). This allowed me to load 65B parameters into system RAM with my Ryzen 7 5800X 8 core/16 thread CPU to perform the operations. The CPU usage while it is processing tokens on llama.cpp looks like an EEG:
While running inference on the CPU was certainly useful for my initial experimentation and the CPU usage graph looks cool, it was exceedingly slow. Even an 8 core/16 thread CPU is ill-suited for AI inference in part due to how it lacks the massive parallelization of graphics processing units (GPUs) but perhaps more importantly due to the system memory bottleneck, which is only 25.6 GB/s for DDR4-3200 RAM according to Transcend.
Video cards, especially those designed by NVIDIA, provide specialized parallel computing capabilities and enormous memory bandwidth between the GPU and video RAM (VRAM). NVIDIA’s CUDA is a very mature system for parallel processing that has been widely accepted as the gold standard for machine learning (ML) and AI development. CUDA is unfortunately, closed source, but many open source projects have adopted it due to its dominance within the industry.
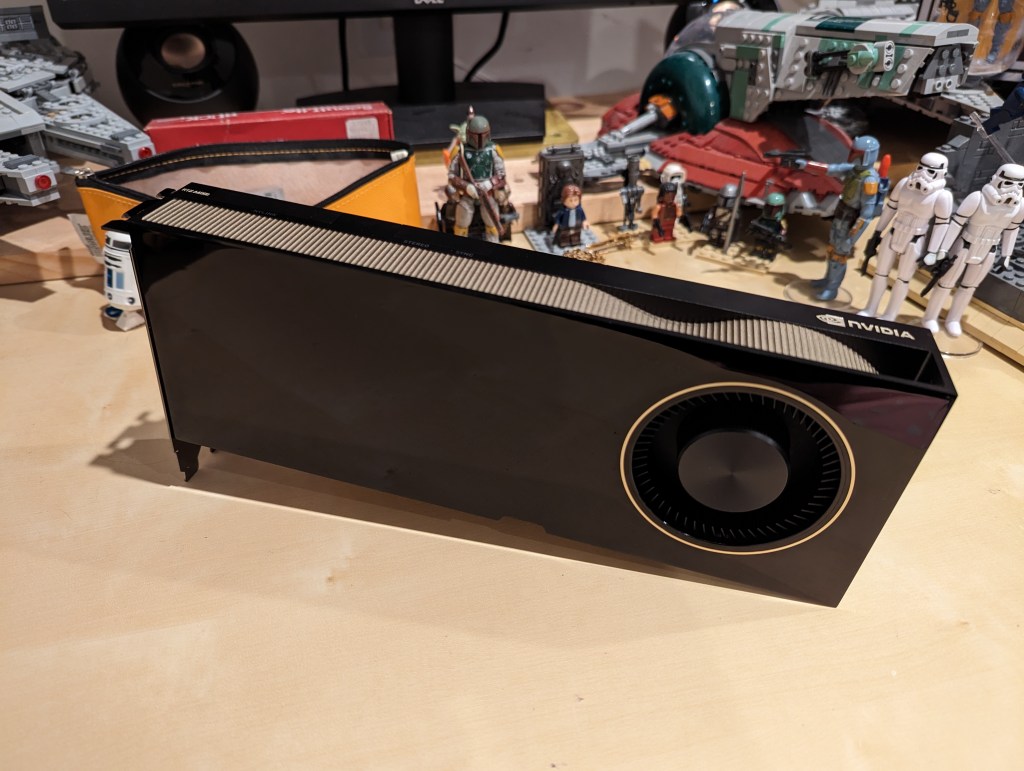
My primary objective when choosing a new video card was that it had enough VRAM to load a 65B LLaMA model (roughly 48GB). One option for doing this is to install two NVIDIA RTX 3090 or 4090 video cards with each having 24GB of VRAM for a total of 48GB. This would solve my needs for running text generation models, but it would limit how I could use image generation models, which can’t be split between multiple video cards without a significant performance hit (if at all). So, a single card with 48GB of VRAM would be ideal for my use case. Three options that I considered were the Quadro 8000, A40, and RTX A6000 Ampere. The Quadro 8000 used three-generation-old Turing architecture, while the A40 and RTX A6000 used two-generation-old Ampere architecture (the latest Ada architecture was outside of my price range). The Quadro 8000 has memory bandwidth of 672 GB/s while the A40 has 696 GB/s and the A6000 has 768 GB/s. Also, the Quadro 8000 has far fewer CUDA cores than the other two cards: 4,608 vs. 10,572 (A40) and 10,752 (A6000). Considering the specs, the A6000 was the better graphics card, but the A40 was a close second. However, the A40, even found for a discount, would require a DIY forced-blower system, because it is designed to be used in rack mounted servers with their own forced air cooling systems. 3D printed solutions that mate fans to the end of an A40 are available on eBay, or one could rig something DIY. But, for my purposes, I wanted a good card with its own cooling solution and a warranty, so I went with the A6000 shown below.
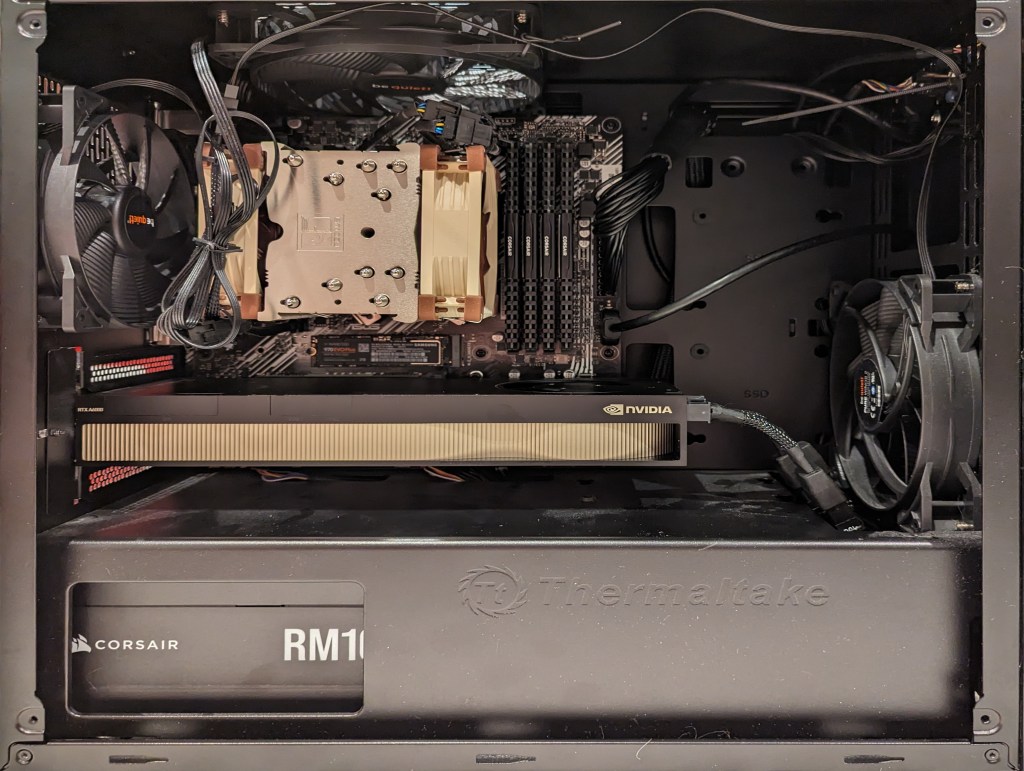
Another benefit to the A6000 over the gaming performance-oriented 3090 and 4090 graphics cards is that it requires much less power–only 300 watts at load (vs ~360 watts for the 3090 and 450 watts for the 4090). Despite this lower power draw, I only had a generic 700 watt power supply. I wanted to protect my investment in the A6000 and ensure it had all of the power that it needed, so I opted to go with a recognized name brand PSU–a Corsair RM1000x. It’s a modular PSU that can provide up to 1,000 watts to the system (it only provides what it is needed–it isn’t using 1000 watts constantly). You can see the A6000 and Corsair PSU installed in my system below.
Now, instead of waiting for 15-30 minutes for a response to a long prompt ran on my CPU and system RAM, it takes mere seconds to load the model on the A6000’s VRAM and generate a response as shown in the screenshot below of oobabooga’s text-generation-webui using the Guanaco-65B model quantized by TheBloke to provide definitions of science fiction for three different audiences. The tool running in the terminal in the lower right corner is NVIDIA’s System Management Interface, which can be opened by running “nvidia-smi -l 1”.
A cute humanoid robot writing at a desk with bookshelf in background. Image created with Stable Diffusion.
Over the weekend, I made some significant updates to the Generative AI and Pedagogy Bibliography and Resource List page, which includes background, debates, teaching approaches, applications, disciplinary research, and a list of online resources. I started it as a place to organize my own research while sharing it back out to others.
It now features a table of contents at the top of the page under the introduction.
I added about 50 articles and books to the bibliography, which now contains 232 sources.
And, I added three links to the resource list at the bottom of the page which brings it to 42 links.
I will periodically add more entries to the list as my own research progresses. But, it’s important to note that this bibliography isn’t meant to be exhaustive.
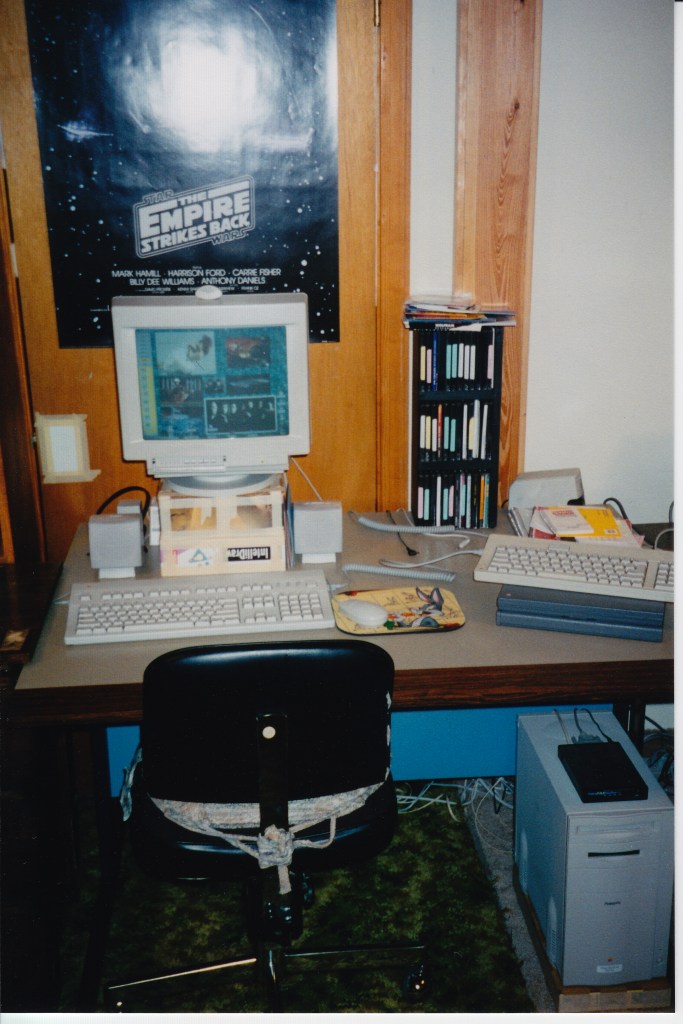
My Apple PowerMacintosh 8500/120 and PowerBook 145B at home. August 1997.
Continuing the work that I started in 2014 when I wrote about the rediscovery of a set of isometric Macintosh icons that I had created and shared in 1997, I wanted to share another rediscovery from February and March 1997 that spans a defunct Macintosh-focused blog called the Power Macintosh Resource Page and Usenet that involves BeOS, winning a magazine, and writing about a hard drive partioning trick that I developed using free BeOS and MacOS applications.
This rediscovery came about after I sent a postcard to another computer enthusiast via Postcrossing.com. I wrote in my postcard about how great I thought BeOS was. She replied that she hadn’t used BeOS before but was interested in it.
I remembered that the way that I came to use BeOS for a time was thanks to a now-defunct technology blog called The Power Macintosh Resource Page. It was operated by Steve Tannehill.
Trevor Inkpen wrote to mention that the Complete Conflict Compendium is about to have its 500,000th visitor. That visitor will win an Apple watch and an Apple hat.
Not to be outdone… ;-)
In the next 2-3 weeks, the Power Macintosh Resource Page will hit the half-million mark. If you send me a legitimate screen shot of the 500,000th hit, I’ll send you a copy of the January MacTech magazine, complete with the BeOS for the Power Mac demo CD-ROM!
Power Macintosh Resource Page, Feb. 1997 Archive, Archive.org Wayback Machine.
There are a few things to unpack here. First, Tannehill mentions Trevor Inkpen’s site visitor context for “an Apple watch and an Apple hat.” That Apple watch prize was not for what we think of as an Apple Watch today. It was an Apple-branded watch that Apple sold through their campus gift shop in Cupertino.
Second, website operators used to pride themselves on how many site visitors they had. This was usually calculated with a public-facing counter enabled by a bit of code offered by a provider that logged page loads containing the code and presented a gif-based numerical counter of the number of page loads. Many of these counters only provided a simple calculation of page loads rather than the more granular information provided by webserver logs and the more advanced metrics of unique visitors, engagement, etc. used today.
Third, like Inkpen’s website with a counter nearing 500,000, Tannehill’s Power Macintosh Resource Page’s counter was also nearing that number. So, he devised a contest to reward the person who was the 500,000th visitor. Unlike Inkpen, Tannehill offered what I considered a greater prize, a copy of the January 1997 issue of MacTech Magazine, which included a CD-ROM installer for the Preview Edition of BeOS.
Before Tannehill offered this prize, I had heard about BeOS from articles in Mac magazines like MacUser, Macworld, and MacAddict. With the burgeoning world of online reporting and news, I had gleaned even more information about it. It sounded like the next big thing, especially in light of Apple’s financial troubles of that era.
Also, I had gotten my PowerMacintosh 8500/120 only a year before, so I had a computer that was capable of running the PowerPC-based BeOS Preview Edition that came with the MacTech Magazine.
After learning about Tannehill’s contest, I first thought that there is no way that I would be lucky enough to be the 500,000th visitor to his site. So, the practical solution was to find a copy of the magazine. I was attending Georgia Tech in Atlanta at the time, so I had access to bookstores with nice magazine selections–the best being Tower Records next Lenox Square Mall in Buckhead.
Unfortunately, I was unable to find a copy of the magazine anywhere. Stores that sold MacTech said that they were sold out. Therefore, my only alternative to obtain a copy of BeOS was to be a super visitor to the Power Macintosh Resource Page. Thankfully, my efforts paid off on 13 Feb. 1997 after I revisited the page late that night and took the required screenshot of my browser window:
13 February 1997:
Jason Woodrow Ellis is the official 500,000th visitor to the Power Macintosh Resource Page! Jason sent the screen shot, so he gets the January MacTech magazine. Congratulations Jason, and thanks to everyone for making this page a success!
Power Macintosh Resource Page, Feb. 1997 Archive, Archive.org Wayback Machine.
Tannehill mailed the magazine to my campus address at Georgia Tech, and after receiving it, I promptly began partitioning my PowerMac’s 2GB SCSI hard drive so that I could boot into Mac OS or BeOS (more on this further below).
And, I would be remiss not to remark on how grateful that I am to Tannehill for offering that magazine as a prize on his website. It was a touchstone in my memories of that era of my life and an important moment in my learning more about computers in general and Macs in particular. I owe him a debt of thanks!
While reading the February 1997 archive page of the Power Macintosh Resource Page, I discovered that I had sent in a report about a presentation by an Apple Representative at the Georgia Tech campus:
25 February 1997:
Jason Woodrow Ellis wrote an interesting note regarding a recent presentation at Georgia Tech on the future of Mac OS:
“Apple Computer, Inc.’s Higher Education Account Executive Steve VanBrackle” gave us a very good outlook for the upcoming Rhapsody and MacOS releases. Mr. VanBrackle told us about the NeXT engineers and how “cocky” they were. He explained that these guys say that they could get the NeXT OS to run on a cellular phone! The point was that they are able to port their OS to anything. …if Mr. VanBrackle is correct the engineers will have an easy time of creating it. First, NeXT had ported their OS to PowerPC several years ago to run on 601’s. Second, the Apple AU/X team had already figured out how to run System 7 apps on top of UNIX. Third, 80% of Copland’s old code will be used with Rhapsody, so Apple did not “totally” scrap those several years of research. Now their task lies in combining these things together which in effect is the “easy” part. …I asked him about Jobs and Wozniak’s role at Apple in respect to all of the rumors about Jobs “taking over.” According to Mr. VanBrackle, they are “10 hour per week advisors to Amelio.” They have no managerial responsibilities and no “code time.”
Power Macintosh Resource Page, Feb. 1997 Archive, Archive.org Wayback Machine.
I vaguely remember this presentation only because I recall receiving a copy of the first Mac Advocate CD-ROM, which contained useful software updates, Apple information, and Apple-related media, and Apple rainbow logo stickers, which I later applied to the rear window of my dad’s Toyota pickup truck that I often drove when I was back home (and earned me vulgar responses from homophobic locals who were not only bigoted but also apparently lived under a rock during the first 20 years of Apple Computer’s existence).
It was exciting to me to find this email excerpt that I had taken the time to write and send to Tannehill. I have no memory of what I reported Steve VanBrackle talking about during his presentation, but the points about what would eventually become MacOS X are very intriguing. Behind these points there were a number of important developments. Apple scrapped Copland, the code-named operating system originally intended to become System 8, Apple’s consideration of purchasing Jean-Louis Gassée’s BeOS as the basis of its next-generation operating system, and Apple’s ultimate decision to purchase NeXT and bring Steve Jobs back to the company.
As a side note, I often signed my online posts using my full name at that time, because I had discovered that there are a lot of Jason Ellis’s in the world. Even in my youth, I had to fight accusations of not having had all of my vaccines or needing additional dental work–things that applied to another guy who shared my first and last names and happened to be a patient at my doctor and dentist. When I got online, I found even more people with my name, and I tried to create an identity distinct from others. Eventually, I settled on Jason W. Ellis.
Returning to an earlier point about multi-booting MacOS and BeOS, I found an old Usenet post (thanks to the remnants of Google Groups, which is unfortunately a poor instance of its former glory) that I had made on 13 Mar. 1997–a month to the day after I had won the MacTech Magazine with the BeOS Developer Preview CD-ROM. I cross-posted this short write-up called “Slick Disk Tricks” to comp.sys.mac.hardware.storage and comp.sys.mac.systems (I just didn’t know any better).
Slick Disk Tricks
Mar 13, 1997, 3:00:00 AM
I was a crazy risk taker. I loaded up the BeOS for Power Macintosh on my 8500/120 with only one hard disk drive. Luckily I already had partitioned it when I first bought the computer. I created three partitions: HD1=340MB, HD2= 830, HD3= 830, and an allotment of 33MB of free space.
When I installed the BeOS, I repartitioned HD1 as a BeOS˛ partition. Because I quickly found that I did not find enlightenment from using Be, I wanted to get rid of it. I just as quickly noticed that Apple’s DriveSetup application would not let me repartition without reformatting. This was not an option. Luckily Be came through.
In order to reclaim my first partition I used Be’s included Mac application called BeOS Partition Utility˛ to rename the BeOS˛ partition to an Apple_HFS partition. Then I restarted my computer and a dialogue comes up at the desktop for me to choose to initialize the new partition or eject it. I opted to initialize it (which took all of five seconds) and suddenly I have my first partition back! No special programs or extra drivers necessary. Just as a precaution, I did use Norton’s Wipe Info application to do a nice government˛ sweep of all previously stored data. (OK, so I cheated a little bit!)
I am about to loose my internet connection at Georgia Tech, so I have been trying to download everything under the sun to play with when I go back home this month. This need of space reminded me of my 33MB of free space. This takes a little bit more time and effort than regaining a BeOS˛ partition (but it is exactly the same procedure, almost). These are the steps that I used. First, I used the BeOS Partition Utility˛ to rename the Apple_Free to BeOS. Next I launched the BeOS from the CD-ROM and initialized this the free˛ partition for use by the BeOS (this gives the partition a name). Next I rebooted my computer after _not_ installing the BeOS and again used BeOS Partition Utility˛ to rename the BeOS˛ partition to Apple_HFS.˛ Now one can see that this is similar to the previous instructions. However when I restarted nothing happened! Well, undaunted, I used Apple’s DriveSetup app to update the disk driver. I rebooted and now my free space is a new partition asking to be initialized. I now have my full hard disk drive available for storage purposes.
One should realize that what I did was very perilous and down right horrific. I don’t have any kind of backup solution or another disk drive to keep files on. Please use caution if you try this technique to reclaim disk space! And, remember, I am loosing my email address shortly so you have no ability for flames or other such nonsense.
While I wrote this with the intent of sharing a neat way to use the BeOS Partition Utility and Apple’s DriveSetup programs to resize and reclaim hard drive space without the need of paid partitioning software, it is an embarrassing piece of writing. However, I try to remind myself that it was something that I wrote about 25 years ago, which puts it in its proper context.
Also, I’m saddened to read that I wrote, “I quickly found that I did not find enlightenment from using Be.” I don’t recall exactly why I didn’t find it enlightening. From my viewpoint now, BeOS was exciting to use and had an excellent user interface (UI). But, I can imagine how it might not have been a daily driver OS due to its development stage and a fewer application options than MacOS. Also, hard drive space cost a premium, so I probably wanted to have the drive space back for other projects that I was working on at the time. So, while my 1997-self might have not found enlightenment from BeOS, my present self recognizes BeOS as something that had the potential to be insanely great (Steve Jobs would probably not appreciate my borrowing his phrase for this case, but I think it applies nevertheless). And I do know that despite my not keeping BeOS installed on my PowerMacintosh, I enjoyed using Greg Landwebber’s BeView to reskin MacOS as BeOS (and, I alternated between BeView and Aaron, for a Copland look–later, I switched to Kaleidoscope). And, I am certain that BeOS left an indelible imprint on my mind for me to think of it to this day, including its incredible design choices–isometric interface icons, tabbed windows, the application dock, and the finger pointer, as well as its amazing under-the-hood developments with its microkernel, preemptive multitasking, multithreading, etc.
I am curious about the phrase that I used: “did not find enlightenment.” It makes me wonder if an advertisement or article about BeOS used that kind of language to describe using it. When I have some time, I’ll look into that with what’s available on archive.org, Google Books, and other places online that might have digital copies of mid-to-late 1990s Macintosh magazines.
A few final notes: Haiku OS is trying to build something new that captures what BeOS once was and could have been. I haven’t had a chance to try it out yet, but I certainly intend to! And, I owe a great deal of thanks to the Internet Archive for the Internet Wayback Machine and Google Groups (despite Google’s mishandling of this invaluable resource), both of which made this personal exploration possible. While many of our digital traces seem to linger, others disappear without the dedicated and important work of digital preservationists.
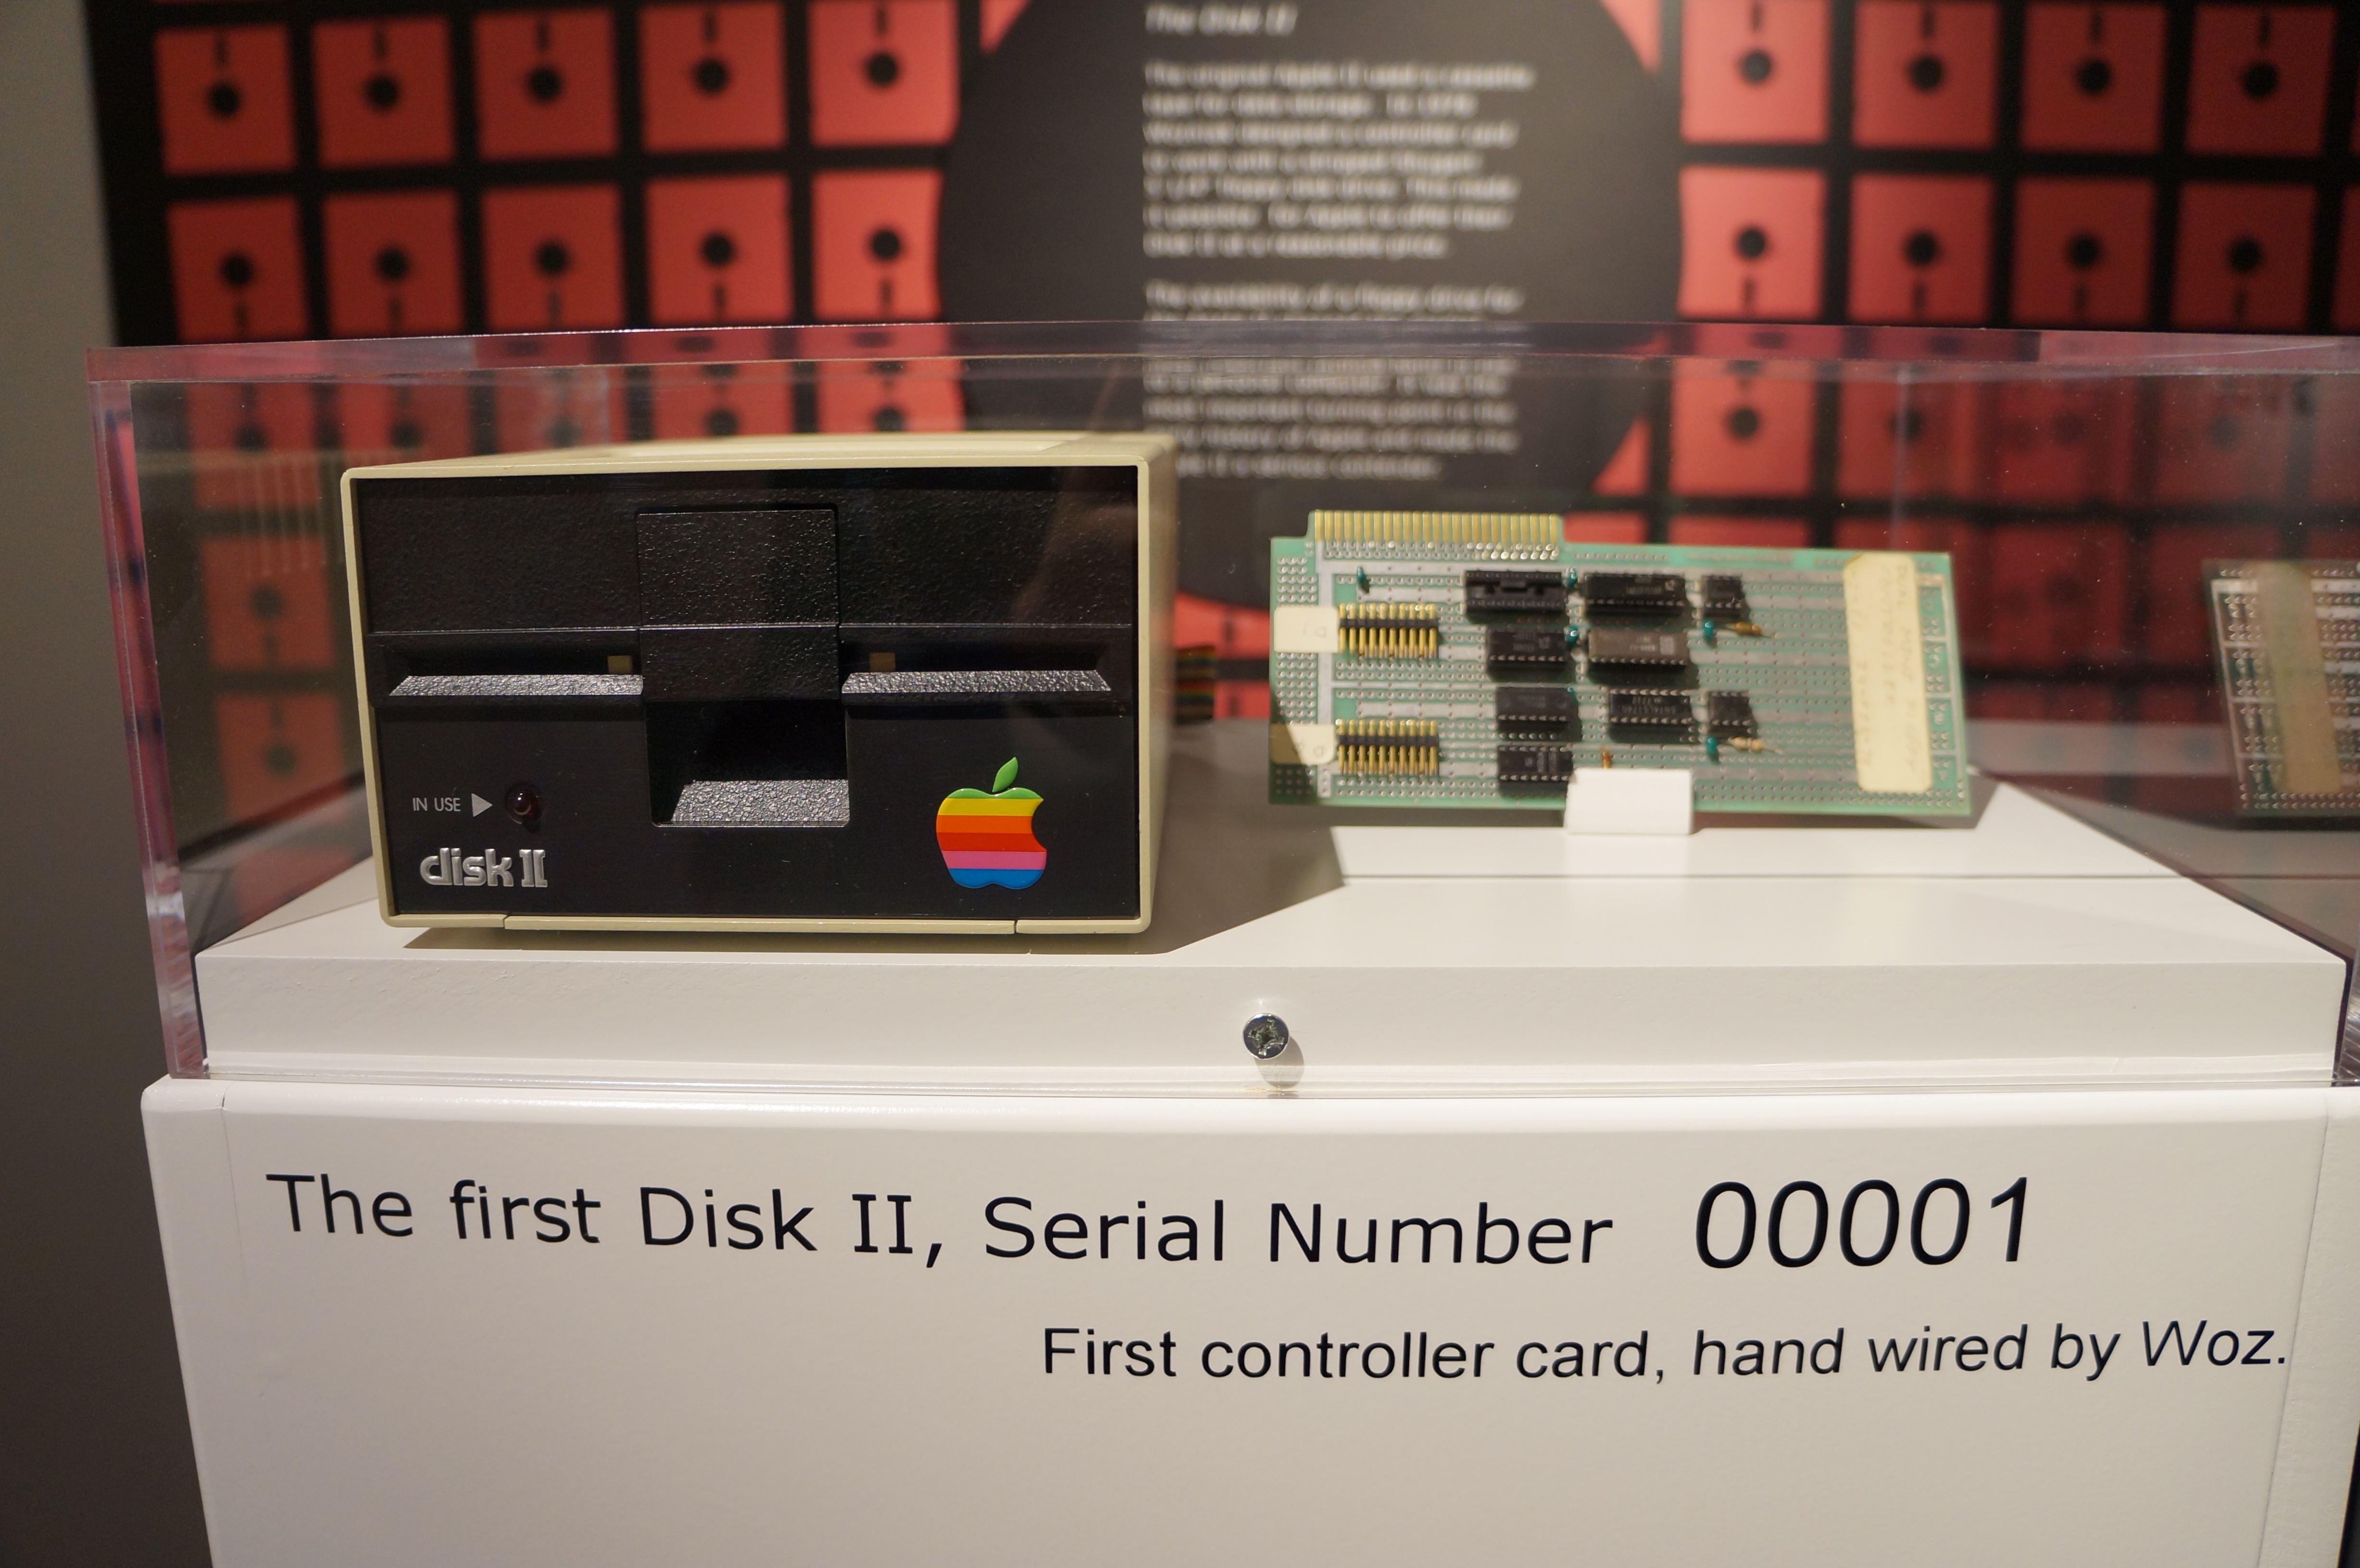
The first Apple Disk II and controller card hand wired by Wozniak. Photo taken at the Apple Pop-Up Museum in Roswell, GA.
Matthew Kirschenbaum constructs a compelling and interesting argument in his book Mechanisms: New Media and the Forensic Imagination (2008). He argues that while new media and computer software might seem ephemeral and intangible, it has in fact physicality, a many-layered history, and emerging archaeological protocols (developed by Kirschenbaum and many others).
However, one section titled “Coda: CTRL-D, CTRL-Z” attracted my attention, because its use of the term “recover” in a story about the debut of the Apple Disk II seemed to imply computer disk data recovery instead of what historically happened, which was the manual rewriting of the software that had been accidentally overwritten during a botched disk copy operation.
Kirschenbaum uses the story of Steve Wozniak and Randy Wigginton’s development of software to control the reading and writing of data to Apple’s Disk II, which was based on Shugart’s 5 1/4″ floppy disk drive, before its unveiling at the 1978 CES in Las Vegas to establish an analogy: “Nowadays we toggle the CTRL-D and CTRL-Z shortcuts, deleting content and undoing the act at a whim. Gone and then back again, the keyboard-chorded Fort and Da of contemporary knowledge work” (Kirschenbaum 69). The idea is that computer facilitate a kind of gone and back again play as described by Freud. Of course, the keyboard shortcuts that he refers to are not universal across platforms or software, but the concept is pervasive. Nevertheless, my focus is not on that concept per se but instead on the Apple Disk II debut anecdote, the terminology surrounding what actually happened, and how that relates to the kinds of work that we do in new media archaeology.
After introducing the story of the Apple Disk II’s debut at CES, Kirschenbaum cites a passage from Steven Weyhrich’s Apple II History website:
“When they got to Las Vegas they helped to set up the booth, and then returned to working on the disk drive. They stayed up all night, and by six in the morning they had a functioning demonstration disk. Randy suggested making a copy of the disk, so they would have a backup if something went wrong. They copied the disk, track by track. When they were done, they found that they had copied the blank disk on top of their working demo! By 7:30 am they had recovered the lost information and went on to display the new disk drive at the show.” (Weyhrich par. 13, qtd. in Kirschenbaum 69).
First, it should be noted that Weyhrich uses the term “recovered” to describe the way that the “lost information” was brought back from the brink of the overwritten disk. Then, Kirschenbaum reads Weyhrich’s account above in the following way:
“Thus the disk handling routines that took the nascent personal computer industry by storm were accidentally overwritten on the very morning of their public debut–but recovered and restored again almost as quickly by those who had intimate knowledge of the disk’s low-level formatting and geometry” (Kirschenbaum 69).
Weyhrich uses the term “recovered” to refer to the software Wozniak and Wigginton had lost during the bad copy operation. Kirschenbaum borrows Weyhrich’s “recovered” and adds “restored” to describe the final state of the software on Wozniak and Wigginton’s floppy disks for use on the CES show floor. When I first read Kirschenbaum’s book, his reading seemed unncessarily ambiguous. On the one hand, Kirschenbaum does not directly say that the two Apple engineers used their knowledge of controlling the disk drive and reading low-level information on the floppy disks to “recover” the lost data–i.e., use the drive and disk technology to salvage, rescue, or retrieve what remains on the disk but otherwise might seem lost to someone with less advanced knowledge. On the other hand, Kirschenbaum’s reading of the incident–“recovered and restored again almost as quickly”–is implicitly aligned with his own project of the physicality of data stored on new media storage devices. One could mistakenly believe that Wozniak and Wigginton had restored the lost data from the overwritten floppy disk.
Steven Wozniak writes about this episode in his autobiography, iWoz: Computer Geek to Cult Icon (2006). Before turning to Wozniak’s later recall of this event in 1978, I would like to look at the two sources that Weyhrich cites on the passage that Kirschenbaum cites in his argument.
Weyhrich’s first of two footnotes on his passage points to page 168 of Gregg Williams and Rob Moore’s 1985 interview with Steve Wozniak titled, “The Apple Story, Part 2: More History And The Apple III” in the January 1985 issue of Byte magazine. In the interview, Wozniak tells them:
“We worked all night the day before we had to show it [the disk drive] at CES. At about six in the morning it was ready to demonstrate. Randy thought we ought to back it up, so we copied the disk, track by track. When we were done, he looked down at them in his hands and said, “Oh, no! I wrote on the wrong one!” We managed to recover it and actually demonstrated it at CES” (Williams and Moore 168).
In this primary source, we see Wozniak using the term “recover” to indicate that they were able to get the demonstration operational in time for CES that day, but what form the “recovery” took place is not explained. Was it data recovery in the technical sense or data recovery in the hard work sense of re-writing the code?
Weyrich’s second footnote on his passage points to Paul Freiberger and Michael Swaine’s “Fire In The Valley, Part Two (Book Excerpt)” in the January 1985 issue of A+ Magazine. While I have been unable to find a copy of this magazine, I did refer to the book that this excerpt was taken from: Freiberger and Swaine’s Fire in the Valley (1984). On page 286, they write in regard to Wozniak and Wigginton’s disk dilemma at CES:
“Wigginton and Woz arrived in Las Vegas the evening before the event. They helped set up the booth that night and went back to work on the drive and the demo program. They planned to have it done when the show opened in the morning even if they had to go without sleep. Staying up all night is no novelty in Las Vegas, and that’s what they did, taking periodic breaks from programming to inspect the craps tables. Wigginton, 17, was elated when he won $35 at craps, but a little later back in the room, his spirits were dashed when he accidentally erased a disk they had been working on. Woz patiently helped him reconstruct all the information. They tried to take a nap at 7:30 that morning, but both were too keyed up” (Freiberger and Swaine 286).
Unlike Wozniak’s “recover” in the Williams and Moore interview above, Freiberger and Swaine use the term “reconstruct” in their narrative about the pre-CES development of the Disk II demonstration software. Unlike the term recover, which means to regain what is lost, reconstruct means to build something again that has been destroyed. Freiberger and Swaine’s selection of this term seems more accurate when considering what Wozniak says about this episode in his autobiography:
“We set up in our booth and worked until about 6 a.m., finally getting everything working. At that point I did one very smart thing. I was so tired and wanted some sleep but knew it was worth backing up our one good floppy disk, with all the right data. . . . But when I finished this backup, I looked at the two unlabeled floppy disks and got a sinking feeling that I’d followed a rote pattern but accidentally copied the bad floppy to the good one, erasing all the good data. A quick test determined that this is what happened. You do things like that when you are extremely tired. So my smart idea had led to a dumb and unfortunate result. . . . We went back to the Villa Roma motel and slept. At about 10 a.m. I woke up and got to work. I wanted to try to rebuild the whole thing. The code was all in my head, anyways. I managed to get the good program reestablished by noon and took it to our booth. There we attached the floppy and started showing it” (Wozniak and Smith 218-219).
In this account, Wozniak says that he is responsible for overwriting the good disk with the bad (as opposed to what he said to Williams and Moore for the 1985 Byte magazine interview), but most important is the terms that he uses to describe how he made things right: “I wanted to try to rebuild the whole thing.” He “reestablished” the program by reentering “the code . . . in [his] head” into the computer that they had on-hand. Wozniak’s word choice and description makes it clearer than in his earlier interview that he had to remake the program from memory instead of attempting to “recover” it from the overwritten media itself. While, it might have been theoretically possible for someone as well versed in the mechanism that by that point he had had a significant hand in redesigning from the original Shugart drive mechanism and controller card and of course his development with Wigginton of the software that controlled the hardware to read and write floppy disks in the Apple Disk II system (computer-controller card-disk drive), Wozniak, who reports throughout his autobiography as an engineer who works things out in head meticulously before putting his designs into hardware or software, took the easiest path to the solution of this new media problem: write out the software again from memory.
Memory, of course, is another tricky element of this story. It was my memory of Wozniak’s exploits that drew me to this passage in Kirschenbaum’s book. My memory of Kirschenbaum’s argument informed the way that I interpreted what I thought Kirschenbaum meant by using this episode as a way of making his Fort-Da computer analogy. Kirschenbaum’s memory of the episode as it had been interpreted secondhand in Weyhrich’s history of the Apple II informed how he applied it to his argument. Wozniak’s own memory is illustrated as pliable through the subtle differences in his story as evidenced in the 1985 Byte magazine interview and twenty-one years later in his 2006 autobiography.
Ultimately, the episode as I read it in Kirschenbaum’s Mechanisms was caught in an ambiguous use of language. The use of certain terms to describe the work that we do in new media–in its development, implementation, or daily use–relies on the terminology that we use to describe the work that is done to others–lay audience or otherwise. Due to the kind of ambiguity illustrated here, we have to strive to select terms that accurately and explicitly describe what it is we are talking about. Of course, primary and secondary accounts contribute to the possibility of ambiguity, confusion, or inaccuracy. Sometimes, we have to dig more deeply through the layers of new media history to uncover the fact that illuminates the other layers or triangulate between differing accounts to establish a best educated guess about the topic at hand.
Works Cited
Freiberger, Paul and Michael Swaine. Fire in the Valley: The Making of the Personal Computer. 2nd ed. New York: McGraw-Hill, 1984. Print.
Kirschenbaum, Matthew G. Mechanisms: New Media and the Forensic Imagination. Cambridge: MIT Press, 2008. Print.
Weyhrich, Steven. “The Disk II.” Apple II History. Apple II History, n.d. Web. 13 Sept. 2015.
Williams, Gregg, and Rob Moore. “The Apple Story, Part 2: More History And The Apple III”, Byte, Jan 1985: 167-180. Web. 13 Sept. 2015.
Wozniak, Steve and Gina Smith. iWoz: Computer Geek to Cult Icon. New York: W. W. Norton & Co., 2006. Print.